Local AI Hosting & Private Models
Deploy, fine-tune, and run state-of-the-art open weights generative models directly on your private infrastructure. Keep your intellectual property, proprietary codebases, and client data completely insulated from third-party APIs and corporate surveillance. Zero per-token tax, zero rate limits, and 100% air-gapped data sovereignty.
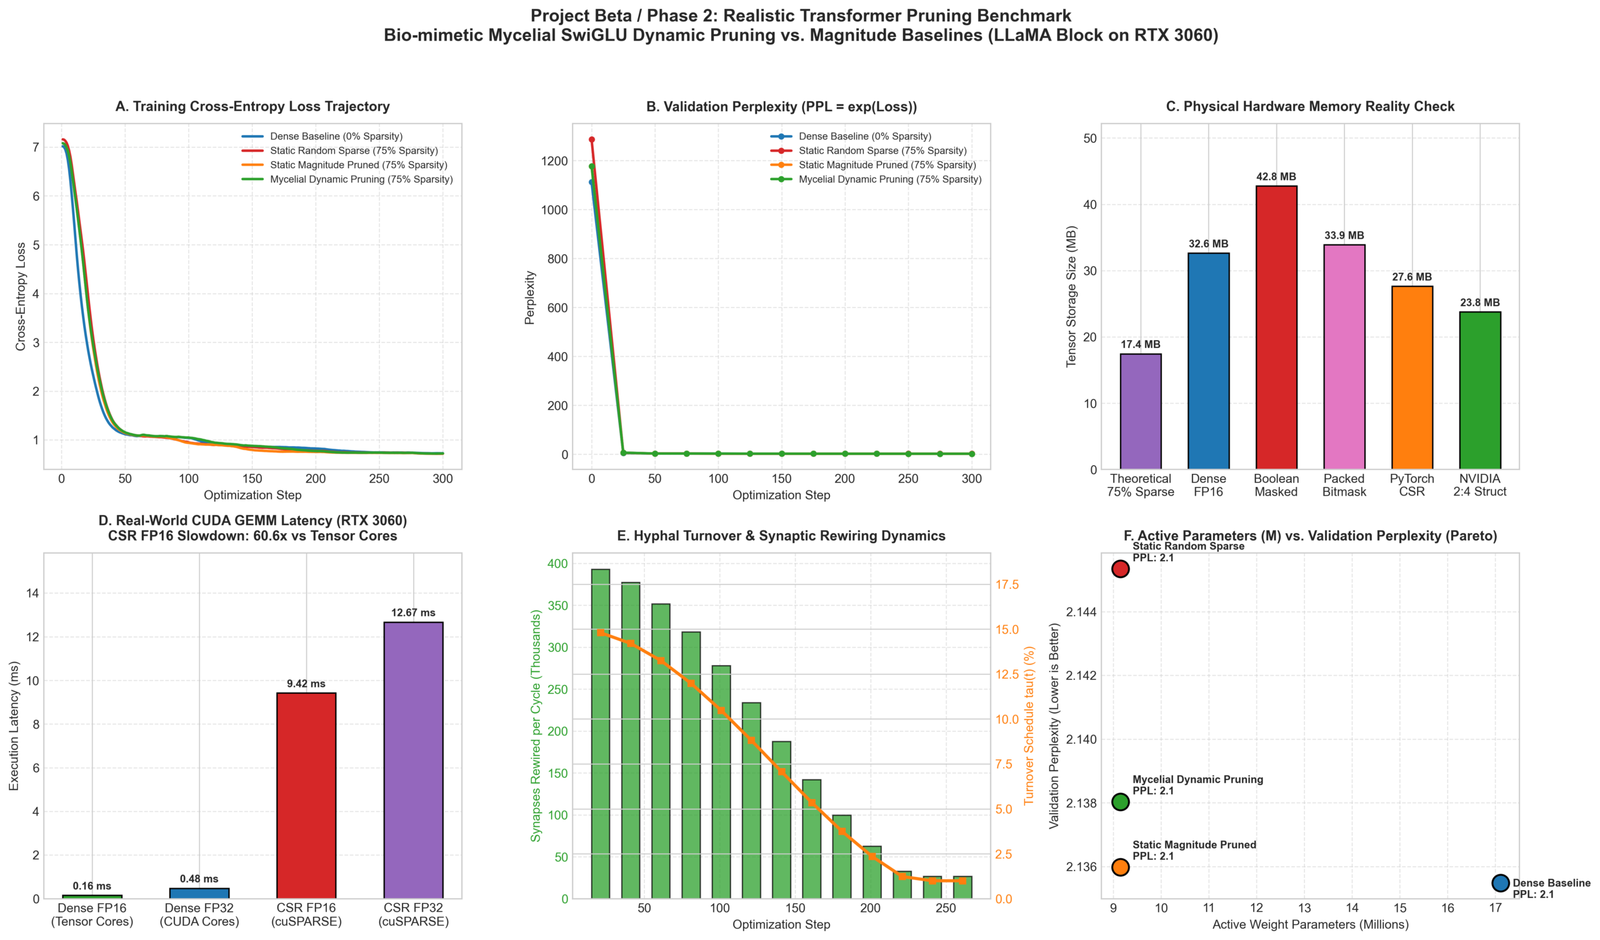 🧠 TRANSFORMER DYNAMIC PRUNING BENCHMARK
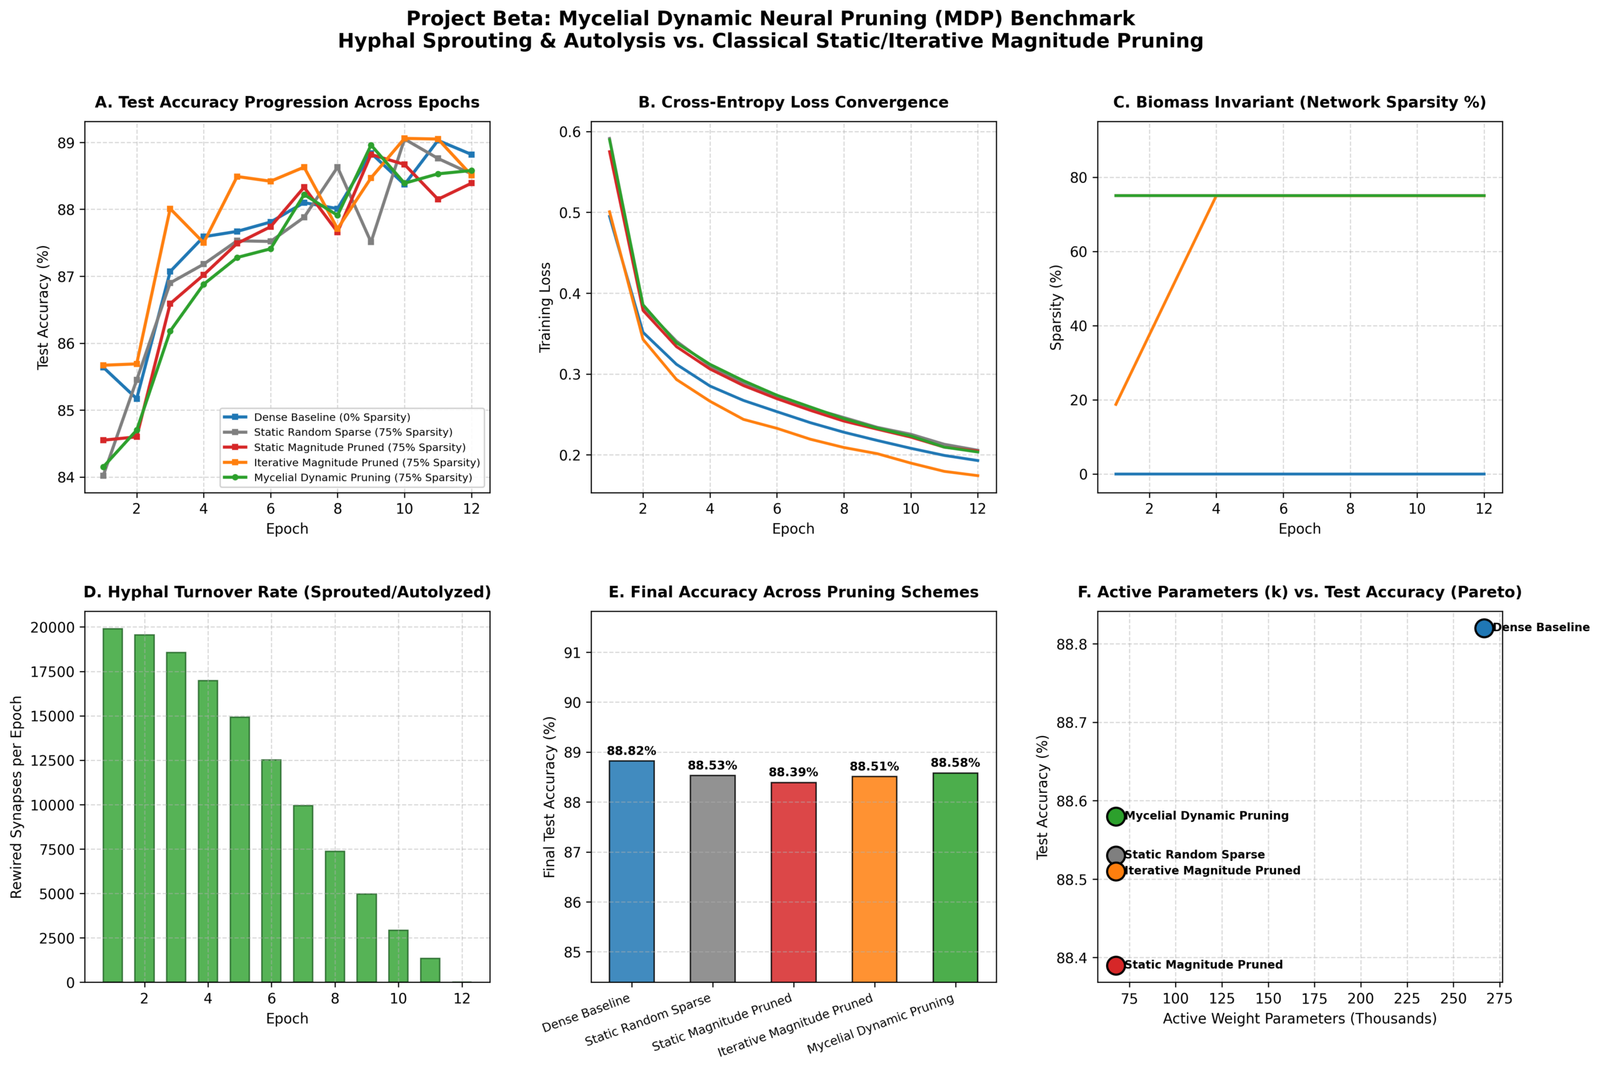
// Bygonepath Labs Sovereign LLM Orchestrator v2.4
// Model loaded in GPU VRAM: deepseek-r1-distill-32b-q4_k_m
// Egress monitor: ACTIVE [0 bytes outbound allowed]
> Click a command below to trigger live local inference simulation...
Private AI Infrastructure
Frontier intelligence hosted on your terms, completely insulated from the surveillance web.
100% Confidential Documents & RAG
Run retrieval-augmented generation on confidential financial records, patient databases, and source code. Embeddings and vector stores never touch third-party servers.
Zero API Costs & No Rate Limits
Say goodbye to thousands of dollars in monthly token charges. Once your hardware is provisioned, running 1,000,000 inferences costs only the electricity to power the rig.
OpenAI-Compatible Drop-In API
Our local daemon provides an OpenAI-compatible REST endpoint. Point your existing applications, IDEs, and business workflows to `localhost:11434` with zero code rewrites.
Deploy Local AI on Your Private Metal
Stop feeding your proprietary data to hyperscaler training sets. We install, tune, and maintain secure local AI instances tailored to your hardware and workflows.